

artificial intelligence
OpenAI, Google, Microsoft and Anthropic Back One Opt-Out Signal for AI Training, but Indian Publishers Want More
OpenAI, Google, Microsoft and Anthropic Back One Opt-Out Signal for AI Training, but Indian Publishers Want More
![]() By Elets News Network - 31 October 2026


Four of the most powerful companies in artificial intelligence, OpenAI, Google, Microsoft and Anthropic, have agreed to honour a single, shared signal that lets website owners say whether their content may be used to train generative AI models. The move, announced on 30 October, replaces today’s patchwork of company-by-company crawler rules with one instruction that participating AI developers have committed to read the same way.
For publishers, enterprises and anyone running a content-heavy website, it is the most significant attempt yet to standardise consent for AI training. In India, however, it lands in the middle of an unresolved legal fight over content that has already been used.
From many crawler rules to one preference
Until now, a site that did not want its pages used for AI training had to block each company’s crawler separately in its robots.txt file, the plain-text file that tells bots which parts of a site they may visit. That meant individual entries for OpenAI’s GPTBot, Google-Extended, Anthropic’s ClaudeBot and others, with each company interpreting the rules in its own way.
The new approach is built on an AI Preferences draft submitted to the Internet Engineering Task Force (IETF), the body that maintains the Robots Exclusion Protocol. It introduces a shared “AI training” preference that a publisher can set once in robots.txt. Participating companies say their crawlers will respect it when they encounter it. The signal covers generative AI training; it is not meant to affect models that perform only non-generative tasks, and it does not change eligibility for ordinary search results.
A staggered rollout
- Anthropic, whose standards lead proposed the shared token at the IETF, says it already supports the signal.
- OpenAI says it will implement it “in the coming months”.
- Google plans to support it in 2027.
- Microsoft will begin honouring the new preferences as Bing crawls from 1 February 2027, and has asked sites to move off its older NoArchive and NoCache tags by 1 March 2027.
Meta has publicly welcomed the idea of a common signal but has not said whether its own crawlers will honour it.
Microsoft splits training from grounding
Microsoft has gone a step further by separating two uses of web content that are often lumped together. Alongside the shared AI Training preference, which can be set for a whole site in robots.txt and overridden page by page, it is introducing a page-level AI Grounding preference. Grounding is the process by which an AI assistant pulls in live web content to inform or cite an answer.
Publishers will be able to allow grounding, disallow it, or choose a new DisallowExtended option, which limits grounding to Microsoft’s own experiences such as Copilot, Microsoft 365 and Bing’s AI features while excluding grounding services Microsoft provides to third parties through its APIs. Microsoft has cautioned that blocking grounding will reduce a brand’s visibility in AI answers, and that allowing either use guarantees neither traffic nor payment.
Why Indian publishers remain sceptical
In India, the announcement is being read against the case the Digital News Publishers Association (DNPA) has pursued against OpenAI in the Delhi High Court. The association, whose members include some of the country’s largest media groups, has alleged that copyrighted Indian journalism was scraped to train ChatGPT, including from sites that had already used robots.txt to ask AI crawlers to stay away.
That is the gap a shared opt-out does not close. The signal standardises consent going forward, but it does nothing about content already absorbed into existing models, and robots.txt itself is voluntary rather than legally enforceable. India’s Copyright Act, dating to 1957, has no AI-specific provisions, which leaves publishers arguing conventional infringement law in court while policymakers prepare the country’s broader AI regulation.
What it means for enterprises
For CIOs and digital leaders, the practical takeaway is that AI content governance is becoming a configuration decision, not just a legal one. Organisations that publish documentation, research, product information or news will need to decide, page by page if necessary, whether they want that material used for model training, for live AI answers, for both, or for neither, and weigh that choice against visibility in AI-driven search.
The shared signal is a genuine step towards clearer rules of the road between AI developers and content owners. Whether it becomes durable infrastructure will depend on how quickly the remaining companies ship support, whether others such as Meta sign on, and how courts and regulators, including in India, settle the question of content that has already been used.
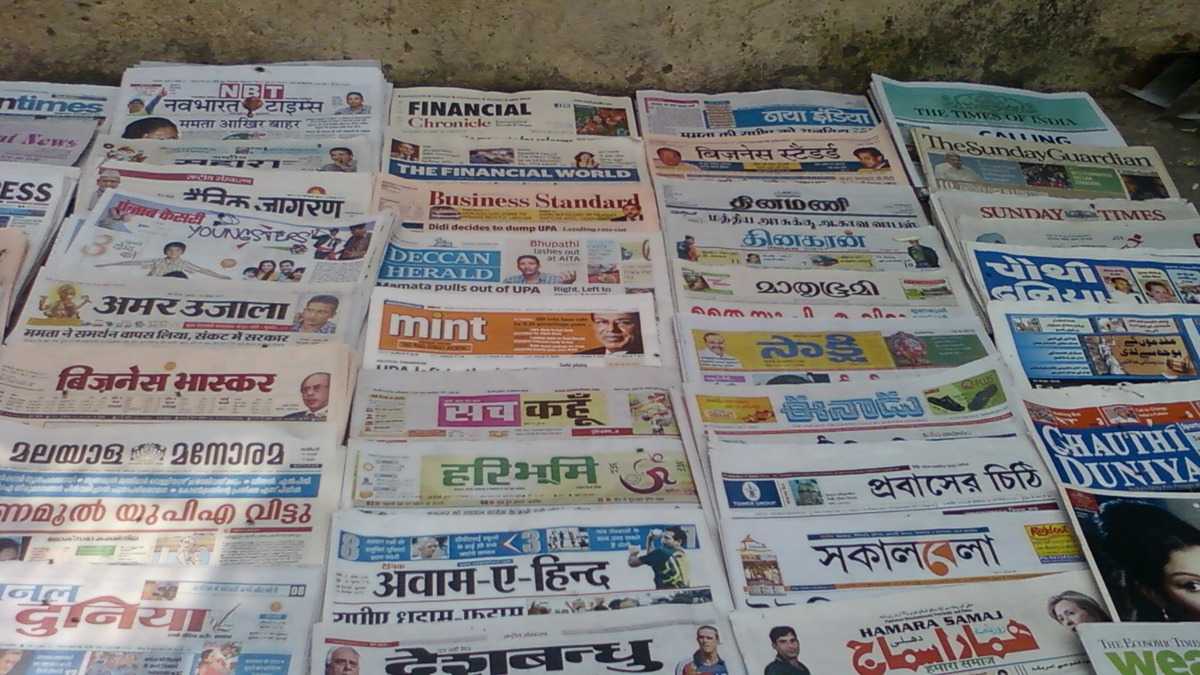
Image: Indian newspapers at a vendor’s stall in New Delhi. Photo: Shajankumar / Wikimedia Commons (CC BY-SA 3.0)
Be a part of Elets Collaborative Initiatives. Join Us for Upcoming Events and explore business opportunities. Like us on Facebook , connect with us on LinkedIn and follow us on Twitter.
"Exciting news! Elets technomedia is now on WhatsApp Channels Subscribe today by clicking the link and stay updated with the latest insights!" Click here!