


artificial intelligence
Sarvam Token Factory Opens India-Hosted AI Inference to All
Sarvam Token Factory Opens India-Hosted AI Inference to All
![]() By Elets News Network - 17 November 2026


Bengaluru-based Sarvam AI on 16 November 2026 opened Sarvam Token Factory to all developers and enterprises. The paid inference service runs Sarvam’s own models and leading open-weight models from other labs on GPU clusters in India, through one OpenAI-compatible API, with prices listed in rupees and zero data retention available on request.
The launch puts an Indian start-up in direct competition with global inference providers at a time when OpenAI’s India inference residency for GPT-6 Luna has made in-country processing a selling point for enterprise AI.
What Sarvam Token Factory offers
Token Factory is the inference stack Sarvam already uses to serve its own products. At launch it serves Sarvam 105B alongside GLM 5.3, GLM 5.3 Flash, DeepSeek V4.1 Flash, DeepSeek V4 Pro, Kimi K3, Kimi K3.1 Pro and Google’s Gemma 4 31B. The product page also lists Qwen 3.8 27B, an EmbeddingGemma 2 embedding model and Sarvam’s Prism decision model.

Customers can choose shared or dedicated GPU capacity. Sarvam says it will add new open-weight models from the day they are released and grow compute as demand rises. Introductory prices, per million tokens and excluding GST, include:

- Sarvam 105B: ₹10 for input and ₹25 for output
- DeepSeek V4.1 Flash Standard endpoint: ₹14 for input and ₹55 for output
- DeepSeek V4.1 Flash Interactive endpoint, built for coding agents: ₹25 for input and ₹105 for output
- Kimi K3.1 Pro, the most expensive model on the list: ₹200 for input and ₹950 for output
How fast is Sarvam’s India-hosted inference?
Sarvam says Sarvam 105B returns its first token in 0.2 seconds and streams 330 tokens per second for a single user. On a 10,000-token prompt, it says Gemma 4 31B starts answering in 0.40 seconds against 2.00 seconds for the only other provider serving that model, and generates 308 tokens per second against 193.
The company also claims it runs India’s largest cluster of Nvidia B200 GPUs and serves more than 450 billion tokens a day on DeepSeek V4.1 Flash alone, with 95.7% of prompt tokens coming from its cache.
These are Sarvam’s own numbers. The company says it measured every provider using a recreation of Artificial Analysis’s method, from a client in AWS Mumbai, taking the median over 72 hours. Testing from Mumbai favours a service hosted in India, and the lead is not universal: in Sarvam’s own charts, Together AI was faster on DeepSeek V4.1 Flash with 10,000-token prompts and level on GLM 5.3. The full method is in the Sarvam Token Factory launch post.
Why it matters for Indian enterprises
For banks, insurers and government bodies, the bigger draw may be where the data goes. Sarvam says prompts run on its GPUs in India and are not passed to foreign model providers. The Token Factory product page lists a 99.95% uptime guarantee under enterprise SLAs, a one-million-token context window, ISO 27001:2022 certification and SOC 2 Type II attestation.
Sarvam also runs the same stack on-premises for what it calls critical institutions and offers that option to enterprises, pitching an AI stack they can own without lock-in. Indian cloud players are moving the same way, as seen in E2E Networks’ pay-per-token Blaze inference service.
The launch follows a busy month for the company, which recently named former Google Cloud India head Sashikumar Sreedharan as President and Chief Business Officer as it scales its enterprise and government business.
Key takeaways
- Sarvam AI made Token Factory generally available on 16 November 2026, serving its own and open-weight models from GPUs in India.
- Introductory pricing starts at ₹10 per million input tokens for Sarvam 105B, billed in rupees.
- Speed claims come from Sarvam’s own tests from Mumbai and have not been independently verified.
FAQ
What is Sarvam Token Factory?
It is Sarvam AI’s paid inference service that hosts Sarvam’s models and open-weight models such as DeepSeek, Kimi, GLM and Gemma on GPU clusters in India, accessed through one OpenAI-compatible API.
Does Sarvam Token Factory keep customer data?
Sarvam says prompts are processed on its GPUs in India and that zero data retention is available on request.
Also read: Sarvam Prism Decision Model Hits 71.8 Score at 44 ms
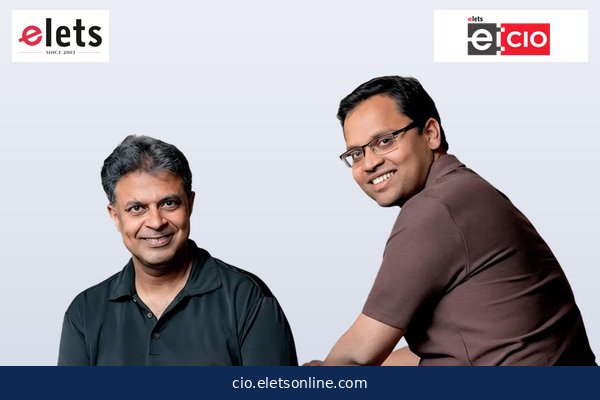
Featured image: Dr. Vivek Raghavan (left) and Dr. Pratyush Kumar, co-founders of Sarvam AI. Photo: Sarvam AI (company website)
Be a part of Elets Collaborative Initiatives. Join Us for Upcoming Events and explore business opportunities. Like us on Facebook , connect with us on LinkedIn and follow us on Twitter.
"Exciting news! Elets technomedia is now on WhatsApp Channels Subscribe today by clicking the link and stay updated with the latest insights!" Click here!